Enterprise AI Training Data Services
Northern Base AI Labs helps enterprise AI teams convert raw images, video, text, audio, LiDAR and business data into model-ready training datasets. Our work combines data annotation services, dataset validation, human-in-the-loop QA and clear delivery controls for production machine learning teams.
What Are AI Training Data Services?
AI training data services prepare the examples that machine learning systems use to recognize objects, understand language, classify events, evaluate risk and improve model behavior. For enterprise buyers, the value is not simply labeling volume. The value is dependable data operations: clear guidelines, calibrated reviewers, audit trails, validation checks and delivery formats your engineering team can use without rework.
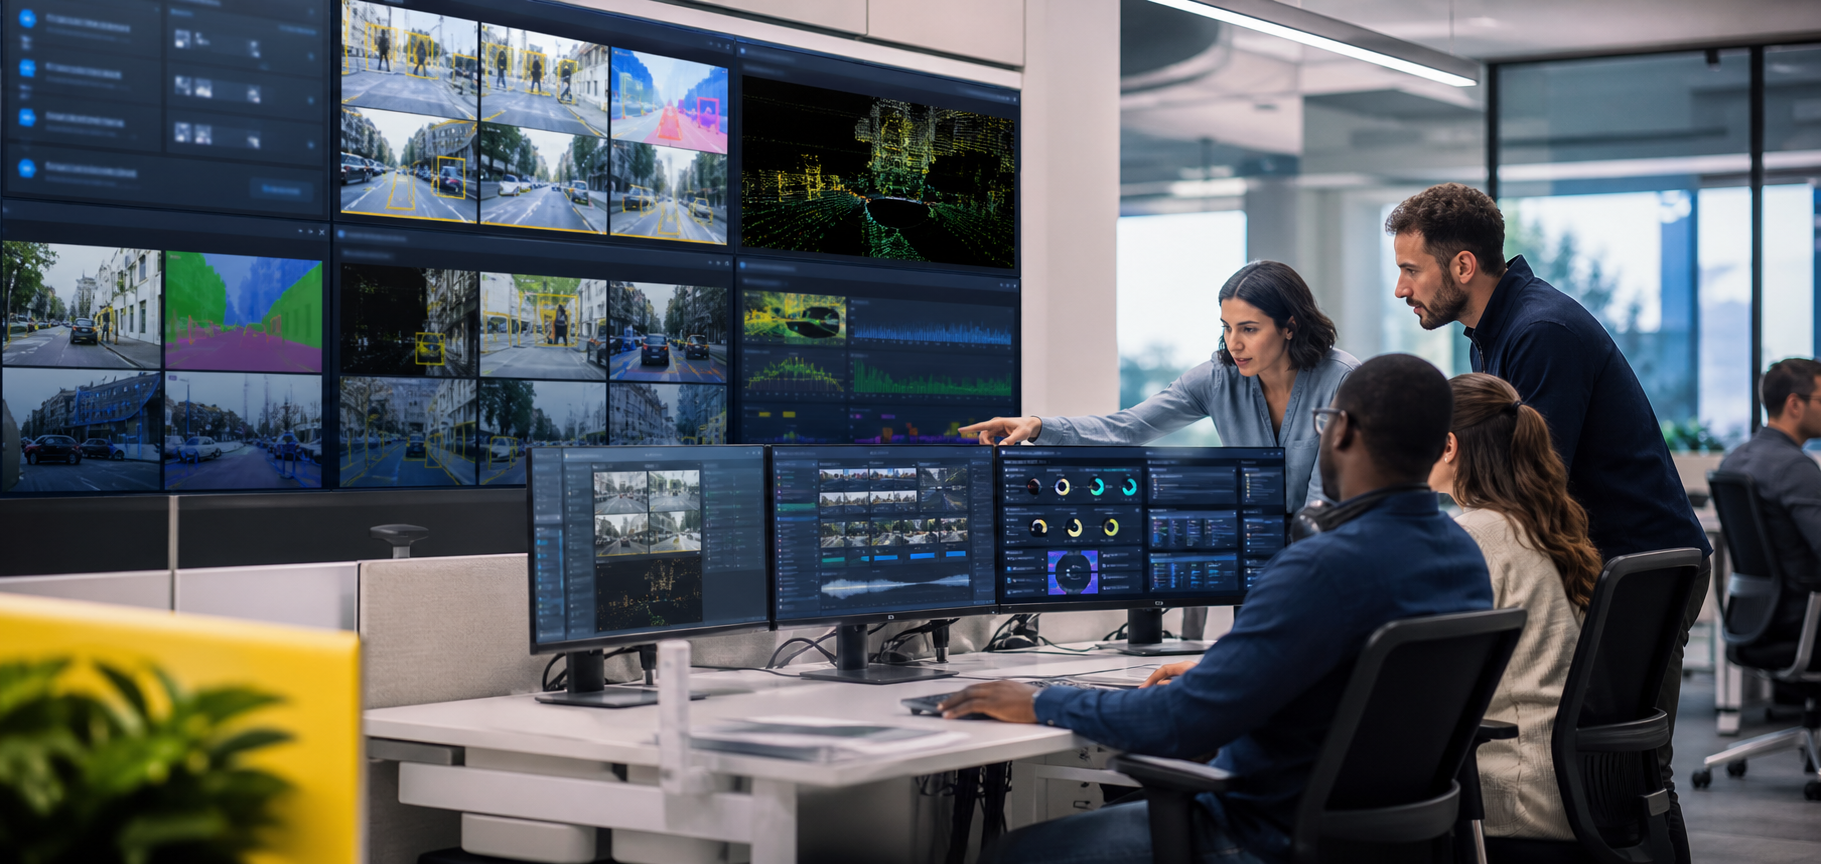
For a US AI team building a computer vision model, that may mean bounding boxes, polygons, semantic segmentation masks, image classification and quality review. For an LLM team, it may mean entity annotation, intent classification, response evaluation, safety categories and human feedback data. For a robotics or automotive team, it may involve video events, point cloud annotation and frame-level QA.
Northern Base AI Labs brings these workflows together as a practical data layer for enterprise AI programs, connecting annotation work to model readiness, quality control and scalable dataset improvement.
AI Training Data Services We Provide
Our services support teams that need training data for model development, evaluation, fine-tuning, production monitoring and continuous improvement.
Image Annotation
Bounding boxes, polygons, keypoints, classification and segmentation-ready labels for computer vision training data and visual QA workflows.
Video Annotation
Object tracking, event labeling, frame review and temporal annotation for autonomous systems, surveillance, sports analytics and industrial AI.
Text and LLM Data
Named entities, intents, sentiment, topics, moderation categories and evaluation data for NLP, LLM training data and enterprise language systems.
Audio and Speech Data
Transcription, speaker labeling, timestamps, call review and speech data annotation for ASR, voice analytics and support automation.
LiDAR and 3D Data
Point cloud annotation, 3D cuboids, object classification and sensor-fusion-ready datasets for robotics, geospatial AI and autonomous vehicles.
Dataset Validation
Sampling checks, reviewer agreement, metadata review, correction loops and data audit services for teams that need trusted model inputs.
Training Data Workflow
A strong dataset is built through repeatable decisions. Our workflow helps enterprise AI teams move from raw data to validated delivery without losing traceability, context or quality.
Requirements
Define model objective, data type, label taxonomy, acceptance criteria, edge cases, delivery format and security expectations.
Guidelines
Create labeling instructions, examples, counterexamples, escalation rules and reviewer notes before production work begins.
Pilot
Run a small batch to test ambiguity, reviewer agreement, annotation speed and whether the instructions match the model objective.
Annotation
Scale labeling with trained reviewers across images, video, text, audio, LiDAR or multimodal datasets.
QA
Review samples, inspect difficult cases, compare reviewer decisions and correct recurring issues before delivery.
Validation
Confirm that labels, metadata, formats and class coverage align with the agreed model training data requirements.
Delivery
Deliver structured datasets in agreed formats for training, evaluation, reporting and downstream machine learning workflows.
Feedback
Use model and QA findings to refine guidelines, update labels, add edge cases and improve the next dataset version.
Human-in-the-loop QA for model-ready datasets
Training data quality is a business risk, not just an annotation metric. Poor labels can create false positives, model bias, unsafe automation and expensive retraining cycles. Our QA process focuses on the errors that matter to AI teams: unclear rules, missing classes, inconsistent reviewers, difficult edge cases and delivery mismatches.
For teams building enterprise AI products, human-in-the-loop QA provides a practical control layer. Reviewers evaluate ambiguity, audit samples, escalate uncertain cases and help convert project knowledge into durable guidelines.
Reviewer calibration
Align annotators on definitions, examples and edge cases before high-volume work begins.
Sample-based audits
Inspect labeled batches for accuracy, omissions, inconsistent classes and formatting errors.
Escalation handling
Route uncertain or high-risk cases for clarification instead of forcing low-confidence labels.
Feedback loops
Turn QA findings into improved guidelines, better reviewer notes and cleaner future batches.
Supported AI Use Cases
Different AI systems fail in different ways. We design training data workflows around the model objective, not a generic labeling checklist.
Computer Vision
Object detection, semantic segmentation, defect detection, visual search, shelf analytics, security monitoring and medical imaging workflows.
Large Language Models
Prompt-response evaluation, entity extraction, intent labeling, topic classification, safety review and LLM data annotation for enterprise use cases.
Autonomous Systems
Video, LiDAR and sensor review for traffic scenes, robotics, geospatial mapping and high-variance physical environments.
Speech and Support AI
Call transcription, speaker labeling, quality scoring, support intent analysis and customer conversation datasets.
Content Safety
Policy labeling, image moderation, video moderation and trust and safety workflows through content moderation services.
Dataset Improvement
Quality audits, drift review, metadata cleanup and dataset curation support for teams improving existing machine learning datasets.
Industry Applications
Our AI training data services support enterprise buyers across industries where accuracy, speed and auditability directly affect product performance.
Healthcare AI
Medical image annotation, clinical text labeling and dataset validation for diagnostic support, patient workflow automation and healthcare computer vision.
Retail and E-Commerce
Product categorization, catalog enrichment, shelf analytics, visual search and customer support data workflows.
Manufacturing and Robotics
Defect detection datasets, production line imagery, robotic perception data and QA review for industrial AI teams.
Autonomous Vehicles
Road scene annotation, traffic event labeling, object tracking, LiDAR review and sensor-fusion training data.
Financial AI
Document labeling, customer support classification, risk categories, fraud review and NLP datasets for financial workflows.
Geospatial AI
Aerial imagery, land-use classification, object detection, infrastructure review and satellite data annotation.
From raw enterprise data to deployable model inputs
Consider a US computer vision team building a retail shelf analytics model. Raw store images contain inconsistent angles, lighting, occlusion, packaging changes and product lookalikes. A generic labeling process may produce boxes, but it may not produce a dataset that helps the model distinguish real inventory conditions.
A stronger workflow starts with business outcomes: detect out-of-stock items, identify shelf gaps, classify products and flag uncertain cases. From there, annotation guidelines define what counts as a visible product, how to label partially hidden items, when to escalate damaged packaging and how to validate category consistency. Our retail detection and classification pipeline shows why visual observations also need operational context. That discipline is what turns annotation into enterprise AI training data.
Business outcome
Labels are tied to the decisions the model must support, such as detection, classification, ranking or escalation.
Dataset coverage
Samples include normal cases, edge cases, poor lighting, different locations and real-world variance.
Quality controls
QA checks focus on label consistency, missed objects, class confusion and formatting readiness.
Model feedback
Production errors can feed the next dataset version through updated examples and refined guidelines.
Why Choose Northern Base AI Labs?
Enterprise AI buyers need a data partner that understands annotation operations and model-readiness. Northern Base AI Labs supports projects from pilot to production scale with practical process controls.
Commercial AI focus
We support AI teams building real products, internal automation and model workflows rather than one-off labeling tasks.
Multimodal coverage
One team can support image, video, text, audio, LiDAR, moderation, segmentation and data audit workflows.
Guideline discipline
We help convert unclear labeling goals into rules, examples and decision paths that reviewers can apply consistently.
Human review where it matters
Our approach keeps humans involved in ambiguity, safety, policy, context and quality decisions that automated checks can miss.
Enterprise communication
Projects are easier to manage when scope, acceptance criteria, questions and delivery expectations are made explicit.
Topical AI expertise
Teams can also review our AI training data services guide, dataset curation guide and human-in-the-loop AI guide.
Frequently asked questions
Answers for enterprise buyers evaluating AI training data and data annotation services.
What are AI training data services?
AI training data services help companies prepare, annotate, validate and structure datasets so machine learning models can learn from accurate, representative examples.
What data types can Northern Base AI Labs support?
We support image, video, text, audio, LiDAR, segmentation, product categorization, content moderation, sentiment and dataset validation workflows.
How does data annotation improve model accuracy?
Annotation gives models clear examples of objects, classes, events, entities, policies or outcomes. Better labels reduce confusion and make evaluation more reliable.
Why is human-in-the-loop QA important?
Human-in-the-loop QA helps catch ambiguous labels, inconsistent reviewer decisions, policy nuance and edge cases that automated checks can miss.
Can you support enterprise pilot projects?
Yes. We can begin with a scoped pilot, define guidelines, review initial quality and then scale the workflow after acceptance criteria are clear.
Do you provide AI training data for LLMs?
Yes. We support text annotation, entity labeling, classification, moderation review and evaluation workflows that can support LLM training data and model assessment.